Mesh rebuild freecad bracket
hard tier · create
The request
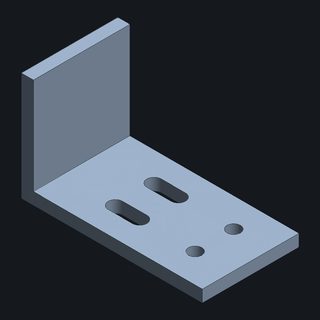
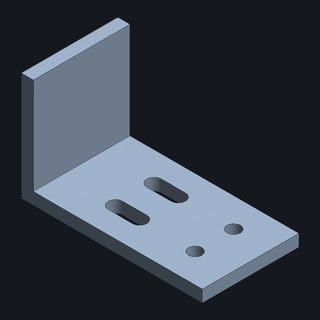
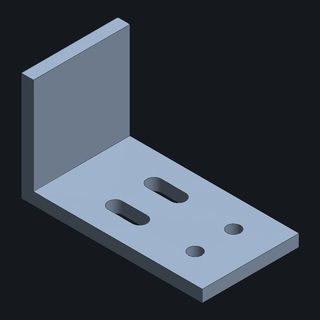
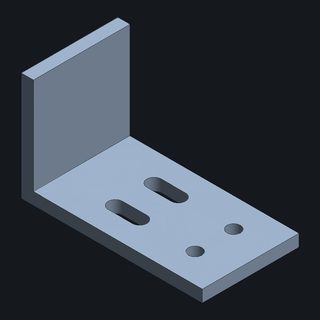
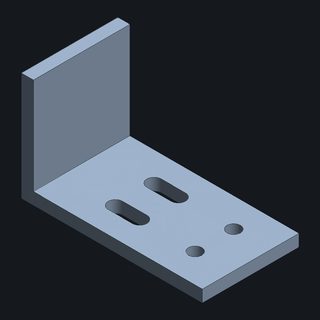
I've attached an STL of an L-bracket exported from a CAD application. Rebuild it as a clean parametric part: one sub-part named exactly `bracket`, matching the mesh's dimensions, hole positions and slots, and standing in the same place as the mesh (Z up, same origin — build it where the import sits, don't re-centre it). Give it three controls — `width`, `thickness` and `holeDiameter` — whose defaults match the mesh and whose ranges cover ±10 mm, 2–8 mm and 3–8 mm. Keep the mesh imported in the part while you work. Measure the mesh first; do not guess.
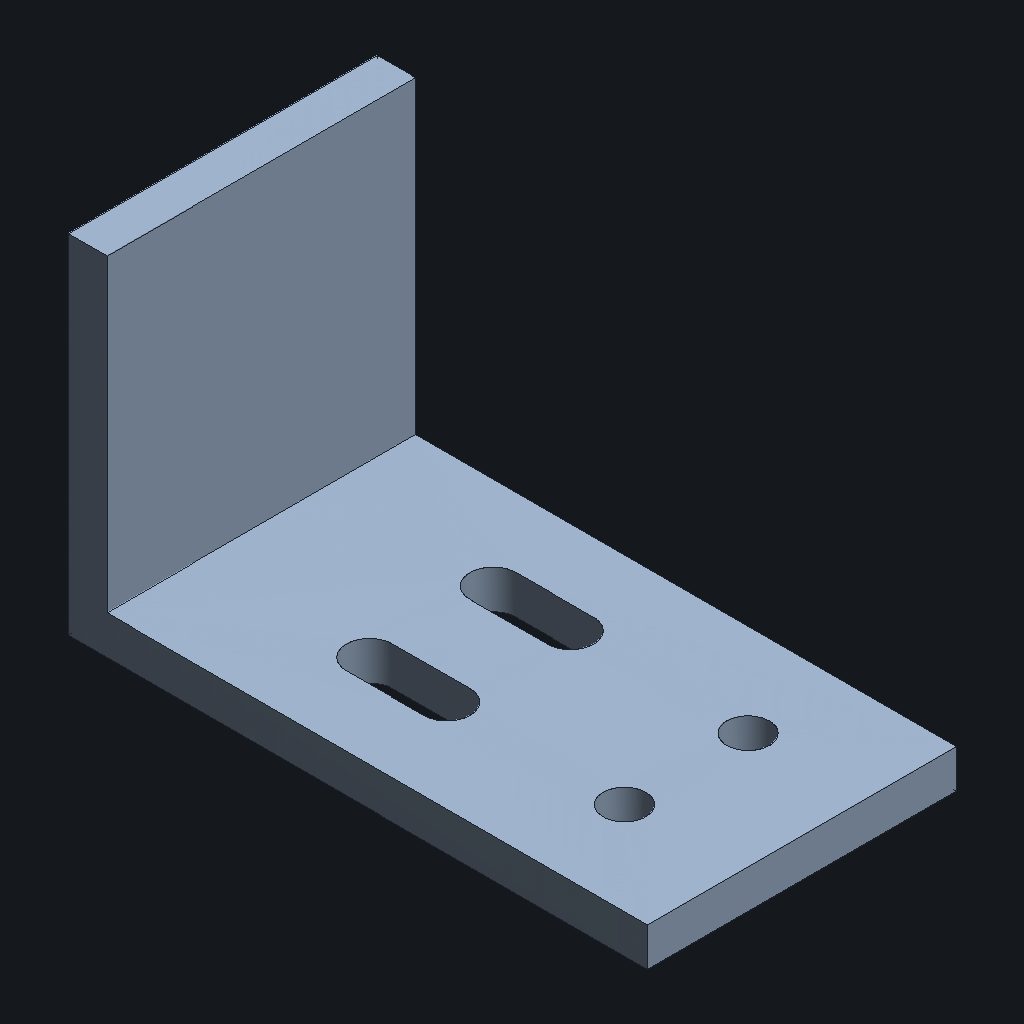
What the AI judge checks
- The overall form matches the reference: the same kind of object, the same silhouette from the matching angle
- Proportions match: the relative sizes of the major dimensions agree with the reference within what the eye can judge
- Every major feature visible in the reference (holes, slots, bosses, tabs, lips) is present in the result
- Those features sit where the reference has them
- Nothing is present that the reference does not show — no decorative or unexplained geometry
- Edges are straight and faces are flat — a CAD rebuild, not a copy of the mesh's facets
- The slots are elongated openings, not round holes
Measured checks
- one sub-part named bracket (gate)
- volume within 3 % of the mesh (gate)
- bounding box within 0.5 mm of the mesh (gate)
- symmetric difference under the measured floor
- holes match the mesh
- the imported bracket is still declared as an import
- asked the oracle at most once
Ranked by hand
One reviewer put one attempt from each model in order, best first, ties left tied.
- #1 tieGemini 3.8 Flash
- #1 tieDeepSeek V4.1 Flash
- #1 tieGPT-6 Luna
- #1 tieGPT-6 Sol
- #1 tieOpus 5.5
- #6Kimi K3 Fast
not acceptable
- #7Kimi K3 (Moonshot)
not acceptable
Parts marked not acceptable fall below the reviewer's acceptable line whatever their order. Ordering by hand decides Human rank and Human rate on the leaderboard; it never affects Overall or Strict.
Every model's attempts
This is an older run. See the current results.
Run hard-baseline-2026-09-232026-09-23commit 6edf19e0spend $212.67 + $43.09 AI judging, 15 unpricedstopped early (interrupted)Other runs: 2026-10-16T18-49-10-hard-compact-2026-10-16, 2026-09-10T19-44-23-baseline-2026-09, 2026-09-04T20-02-10-stage2-hard-cases, 2026-09-04T19-48-31-screen-14-fixed