Which models can actually do CAD?
7 models, 27 tasks, 567 attempts. Each attempt is graded on whether it built, on measured geometry, and on a checklist an AI judge answers from the renders. Click any number to open the attempt behind it.
Where the score and the reviewer disagree
Overall gives partial credit at every layer, so once every model can do most of a task the scores bunch: this run's seven sit inside 4.1 points. Where the two orders below cross, the score is missing something the reviewer saw.
All models
| # | Model | Quality | Cost and time | Overall | Strict | Human rank | Gate pass |
|---|---|---|---|---|---|---|---|
| 1 | Sonnet 5.5Anthropic | 91 | 63% | 49% | 96% | ||
| 2 | GPT-6 SolOpenAI | 90 | 53% | 44% | 93% | ||
| 3 | GPT-6.1 SolOpenAI | 88 | 63% | 41% | 93% | ||
| 4 | Opus 5.5Anthropic | 88 | 54% | 54% | 93% | ||
| 5 | Gemini 3.8 FlashGoogle | 88 | 67% | 60% | 93% | ||
| 6 | Haiku 5.5Anthropic | 88 | 57% | 41% | 91% | ||
| 7 | Gemini 4 ArgonGoogle | 87 | 68% | 61% | 96% |
Overall gives partial credit at every layer, so the top of the board bunches. Strict counts only the attempts that got everything right. Gate pass is the share whose part was watertight, hole-correct and overlap-free. Hover any bar for its number. Ties break by cost, then time. In Quality, the bar marked with a person is one reviewer's ranking of the cases they ordered by hand. First place is 100%, last is 0%, ties share, and the tick marks 50%. That reviewer marked some first attempts unacceptable: Gemini 3.8 Flash 96%, Haiku 5.5 96%. Neither affects Overall or Strict.
Browse the tasks
Hard
 608 bearing seat
 Bottle neck adapter
 Cable clip
 Drawer divider
 Extrusion 2020 end cap
 Laser box printed hinges
 Mesh add tabs
 Mesh holder holes
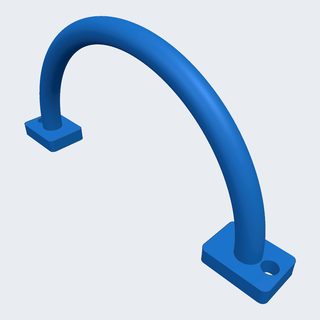 Mesh rebuild blender handle
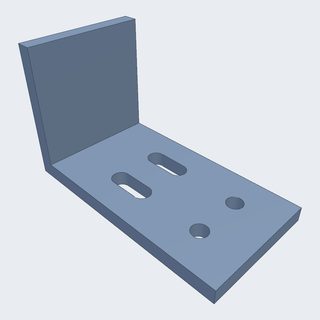 Mesh rebuild freecad bracket
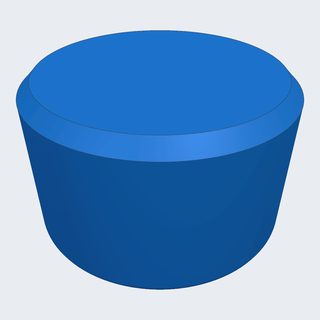 Mesh rebuild freecad knob
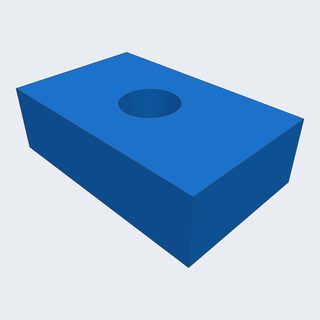 Mesh rebuild scan
 Mesh socket mount
 Nema17 face mount
 Photo cluttered real
 Photo knob
 Photo knob oblique
 Photo lid
 Photo motor bell
 Photo motor bell unstated
 Photo resistor
 Rpi4 tray
 Bracket second mount
 Enclosure build up
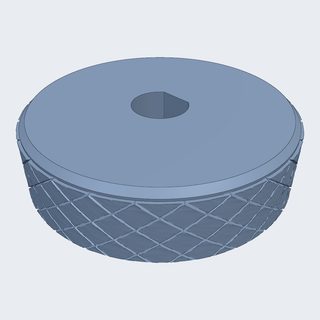 Knob then widen
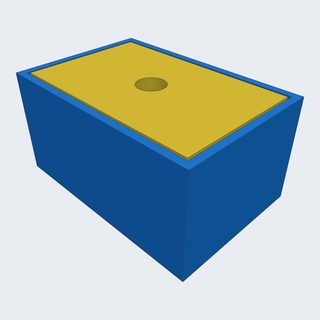 Lid fit and finger hole
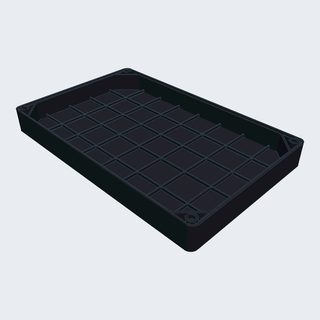 Photo lid then centred
How the score is made
Built 30%, measured geometry 50%, AI judge 20%. A failed gate zeroes geometry for that attempt. The AI judges are Opus 5.5 and GPT-6 Sol. Read the methodology.